Your AI agent answers correctly. Does it sound human?
Correct answers don't stop customers from asking for a human. Customer experience always came down to how something was said, not just what was said. CXWolf measures that, giving you a Text Score and Voice Score, validated against real human raters.
Early access for teams building on Vapi, Retell, and Bland.
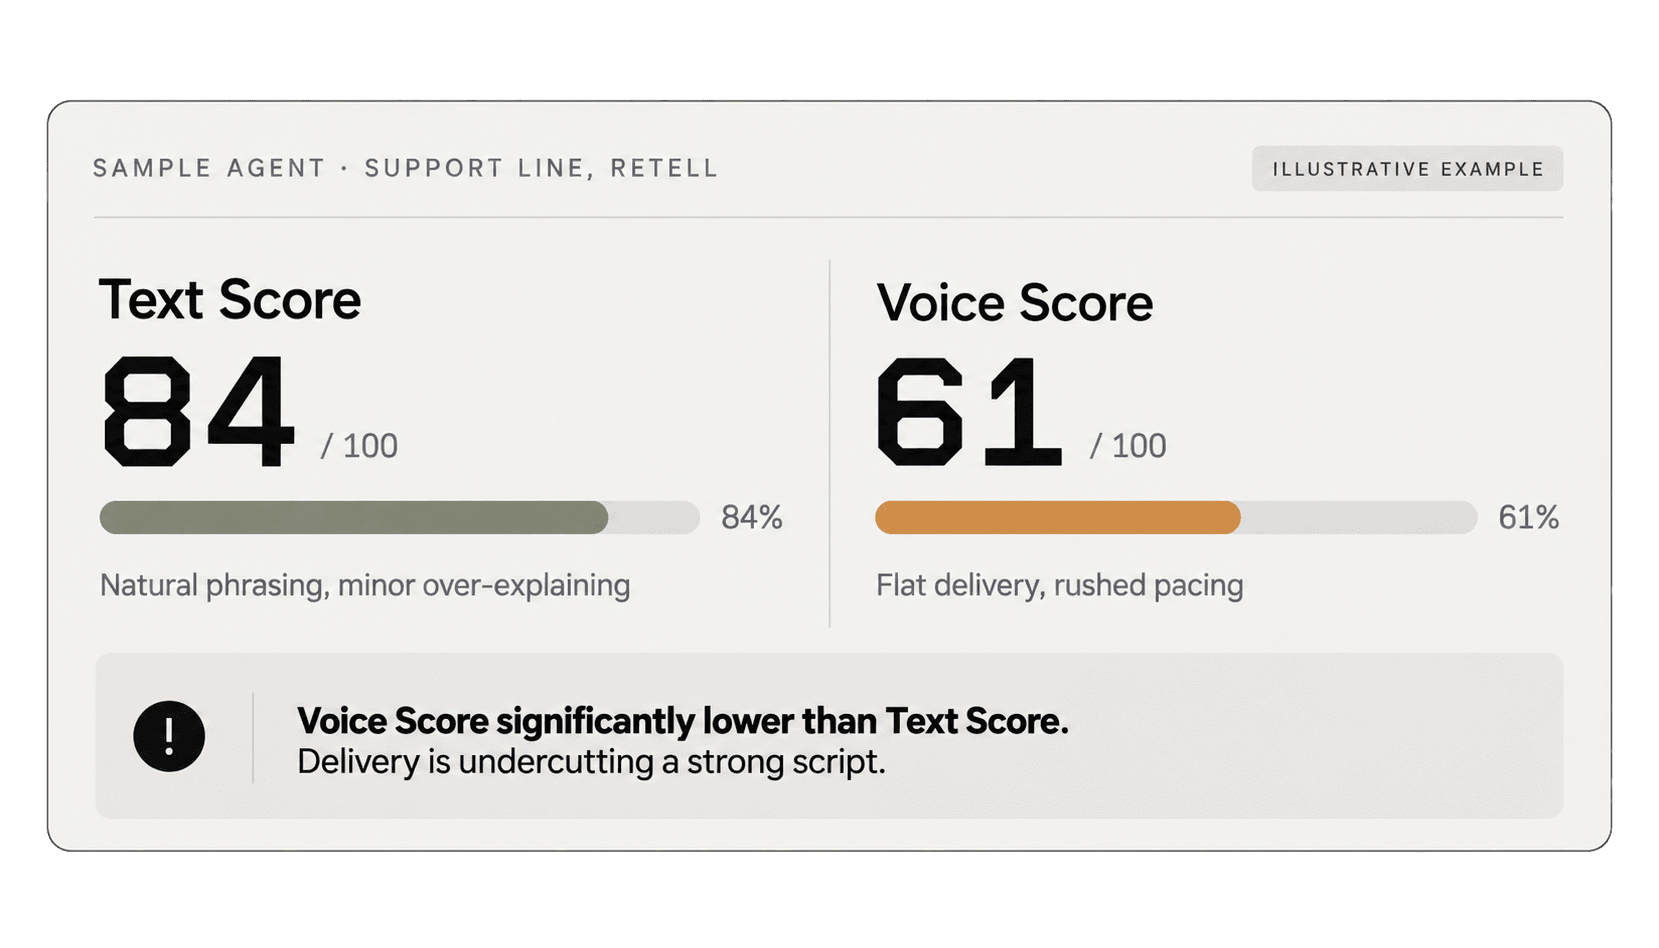
A 20+ point gap between scores is common when delivery lags behind a well-written script.
This was never really about the tech
Fewer complaints. Higher resolution rates. Customers who don't ask for a human the second something feels off. That's not a technical goal. It's a customer experience goal, and it's the same one companies have chased for decades with human agents, now showing up in a new form. The tools got smarter. The measurement didn't catch up.
Correctness gets tested. Tone doesn't.
Every voice and chat agent framework will tell you if your bot got the right answer. None of them tell you if it sounded stilted, robotic, or off-puttingly artificial while doing it. That's often the difference between a customer trusting the interaction and hanging up.
Human-sounding and correct are two different problems. CXWolf measures the one nobody else is measuring.
Two scores, validated against real people
Text Score
How natural the language reads
Word choice, phrasing, pacing, and conversational rhythm, scored on the transcript itself and independent of audio.
Voice Score
How natural it sounds out loud
Prosody, timing, and delivery. These are the things that only show up once text becomes speech.
Both scores are calibrated against ratings from real human listeners and readers, not another model's opinion of itself. Read the full methodology.
Illustrative example
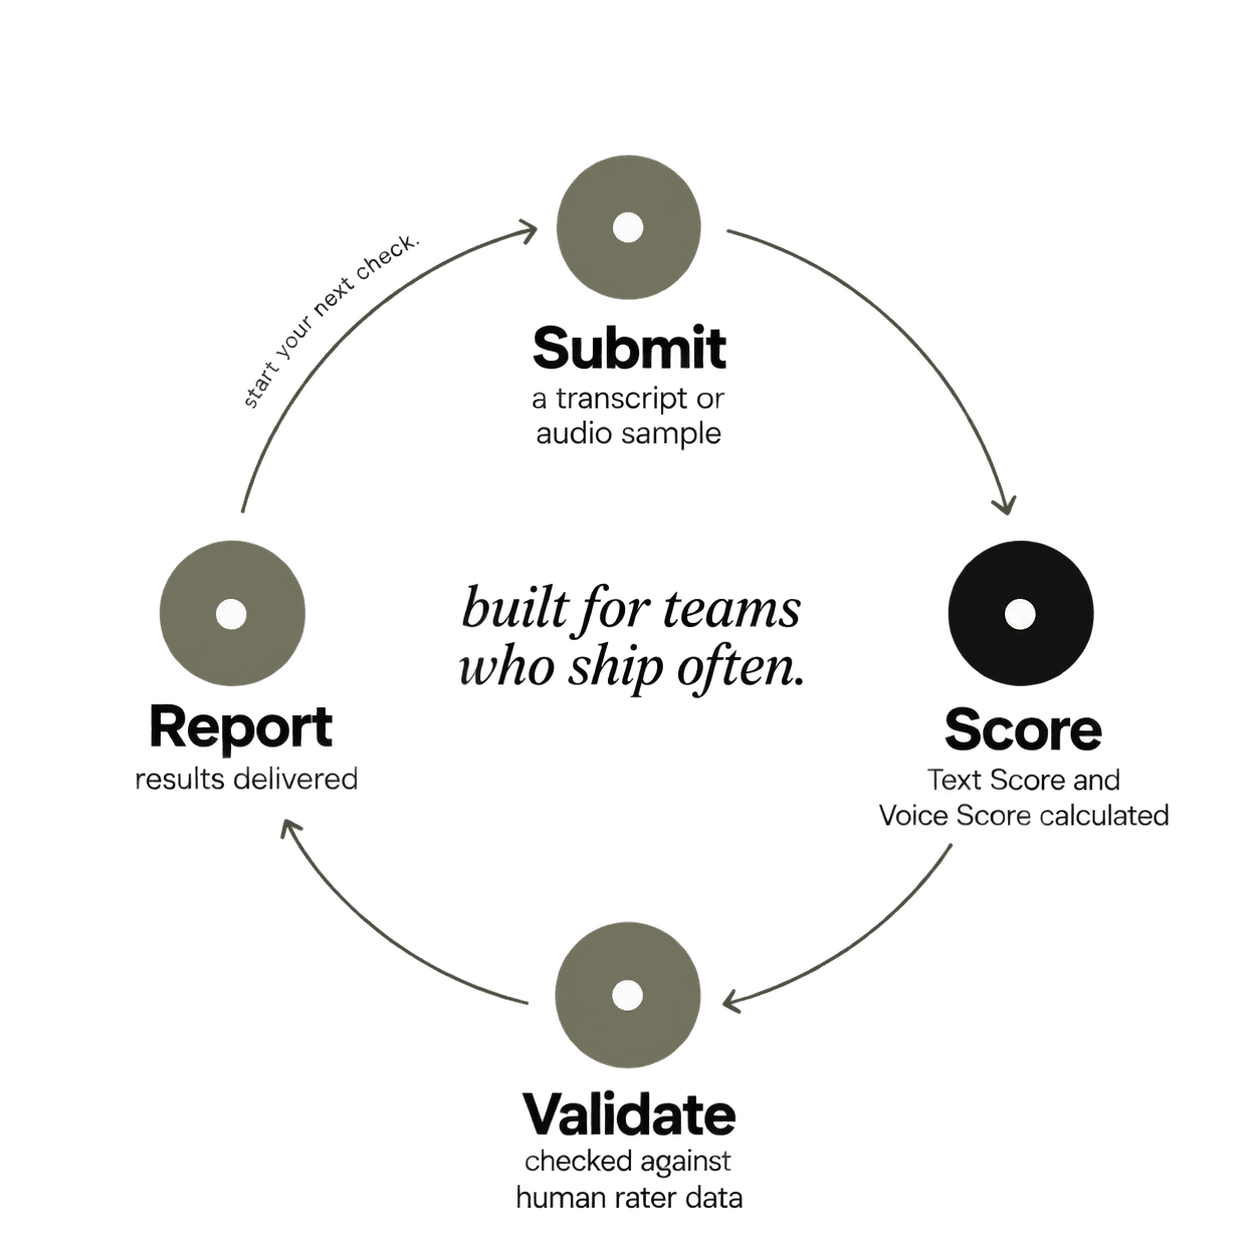
Submit a transcript or audio sample. CXWolf calculates a Text Score and Voice Score, both checked against real human rater data.
You get a report showing exactly where the agent needs work.
See it in action
This is the actual analysis workflow. A developer points CXWolf at a session file and runs a single command.
Text Score and Voice Score come back in seconds, each calibrated against real human raters, not another model's judgment.
Built for teams shipping voice and chat agents
Vapi, Retell, and Bland builders
Ship a prompt or model change and know, in numbers, whether it made your agent sound better or worse.
CX and support leaders
Set a quality bar for automated interactions the same way you set one for human agents.
Agencies and consultancies
Give clients an objective score instead of a subjective opinion about whether the agent sounds ready.
Robotic-sounding agents get escalated. Human-sounding ones don't.
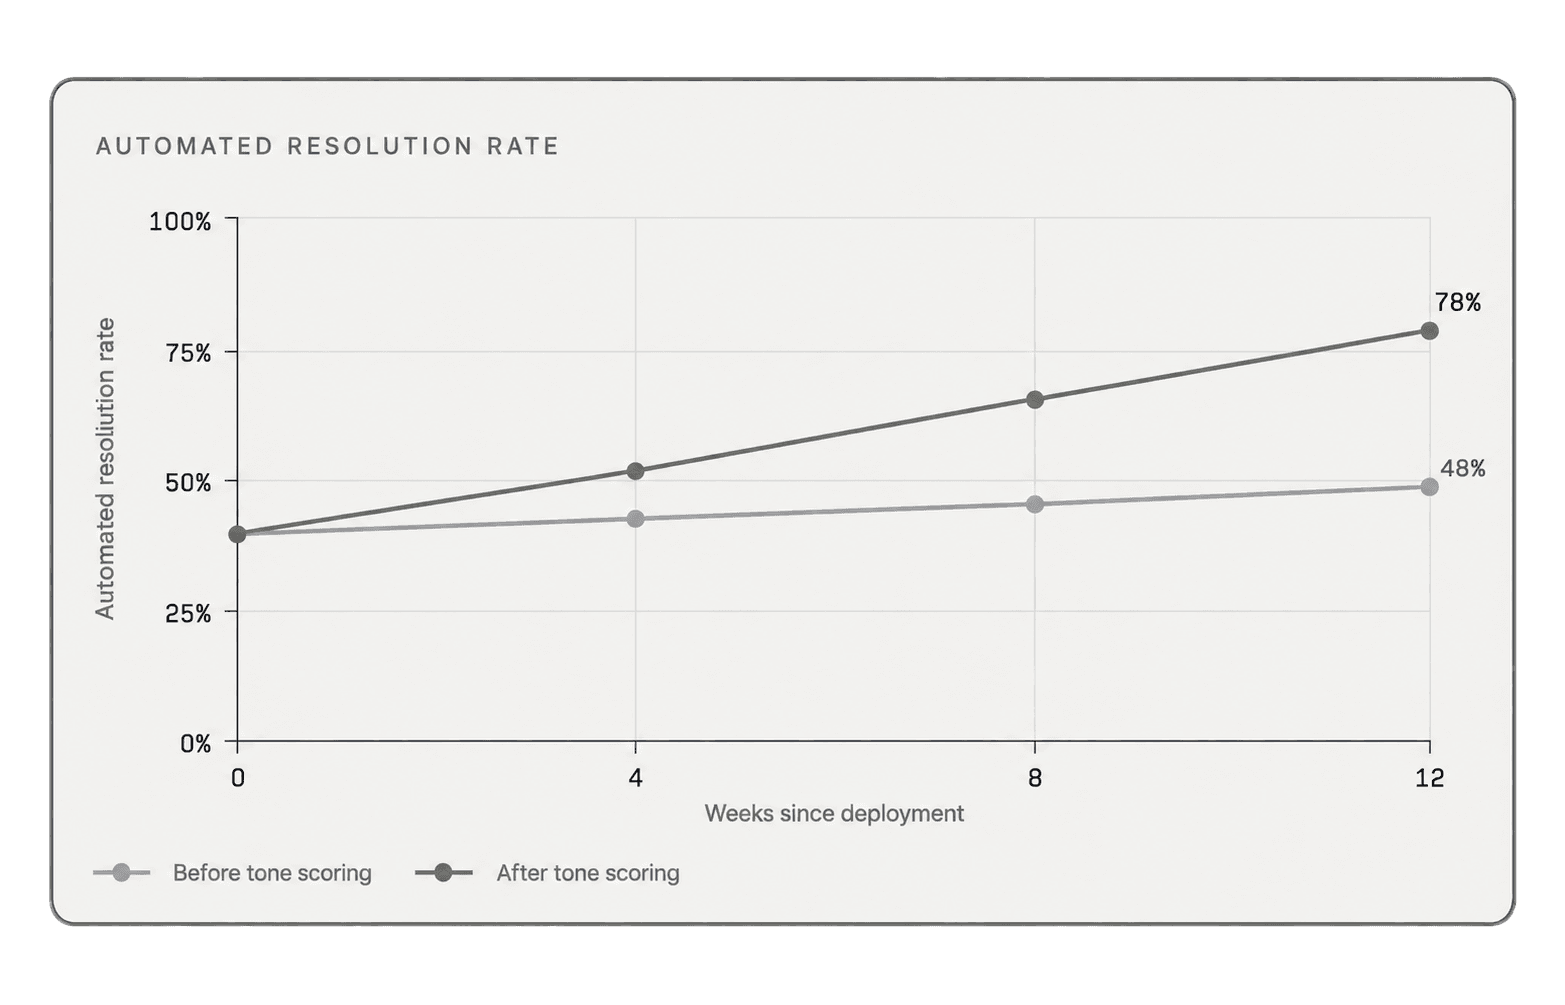
When customers don't trust an automated interaction, they ask for a human. That's not a model failure. It's a tone failure, and it's measurable.
The graph shows automated resolution rate climbing after tone scoring is introduced. Agents that sound robotic get escalated to human agents more often, quietly inflating headcount and cost even when the underlying answers are correct.
Why this matters
I spent my career on the other side of this problem, leading customer experience teams, sitting inside the escalations, the complaints, the moments where trust broke down between a company and the person on the phone. I was recognized as one of the top 10 Chief Customer Officers in the country for that work.
When AI agents started taking those same conversations, I noticed something familiar: the same failure patterns, wearing new technology. Companies were shipping agents that answered correctly and still lost the customer, because how something is said matters as much as what is said. That's not a new insight in customer experience. It's the oldest one there is.
CXWolf is that decade of pattern-recognition, turned into a number you can actually track.